 What's New?
Document Actions
Domain Adaption for Genomic Sequence Analysis
| Supervised learning methods are machine learning techniques that use a set of labeled training examples (x_i; y_i) to infer a model that generalizes well to unseen examples x, and therefore allows to make predictions y for these instances. One of the underlying assumptions is that training and test data are drawn from the same distribution. However, in real-world applications, and specifically in computational biology, one often faces the situation that little or no training data is available for the problem of interest (the target domain), whereas a large corpus of labeled data exists for a related but different problem (the source domain). While it is highly desirable to exploit the labeled source data points to improve performance on the target domain, it clearly violates the basic assumptions of machine learning. Methods to tackle this so-called domain adaptation problem have recently caught increasing attention in the machine learning community and are subject of consideration in this work. In particularly we examine their effectiveness for the problem of splice site prediction across different organisms with varying evolutionary distance. | 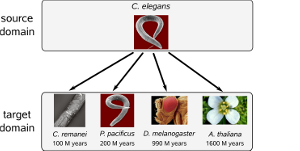 |
People specializing in this area
Alumnae and Alumni
Gabriele Schweikert, Ph.D.
Publications
-
Widmer, C, Leiva, J, Altun, Y, and Rätsch, G (2010).
Leveraging Sequence Classification by Taxonomy-based Multitask Learning
In: Proc. RECOMB'10.
 Printable file
-
Schweikert, G, Widmer, C, Schölkopf, B, and Rätsch, G (2008).
An empirical Analysis of Domain Adaptation Algorithms
In: Proc. NIPS 2008. Advances in Neural Information Processing Systems.
/raetsch/suppl/genomedomainadaptation
Printable file
-
Widmer, C (2008).
Domain Adaptation in Sequence Analysis
Diplomarbeit, University of Tübingen.
Printable file
